 Sabbir Amin
I wanted to know how little a coding agent needs. Not a toy. Something that reads a project, edits files, runs the tests, and asks before it changes anything. So far the answer is one Python file with about 620 lines of code and no dependencies. It is called kidwit. This post is the case study: what it does, how it was built, and the bugs that taught me the most.
What it does
You run kidwit "fix the failing test" in a project folder. The agent lists files, searches, reads, edits, and runs commands until the job is done. It works with Anthropic or any OpenAI-compatible API. That covers DeepSeek, Kimi, OpenRouter, and local servers such as Ollama.
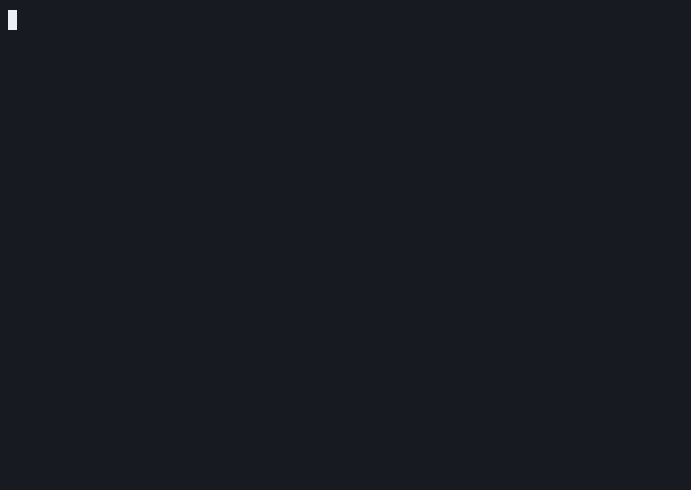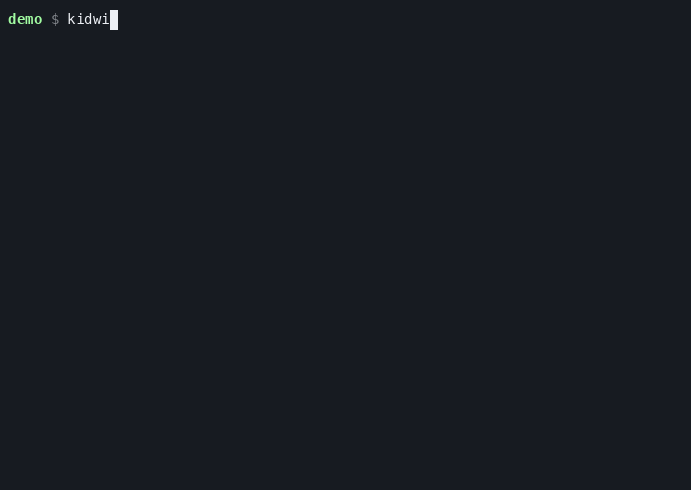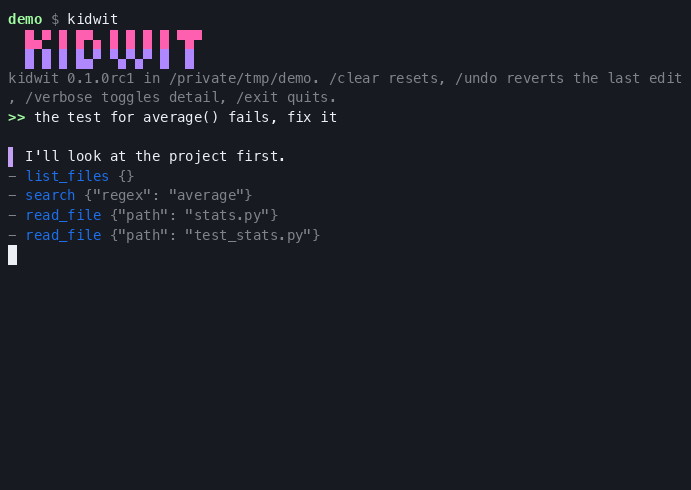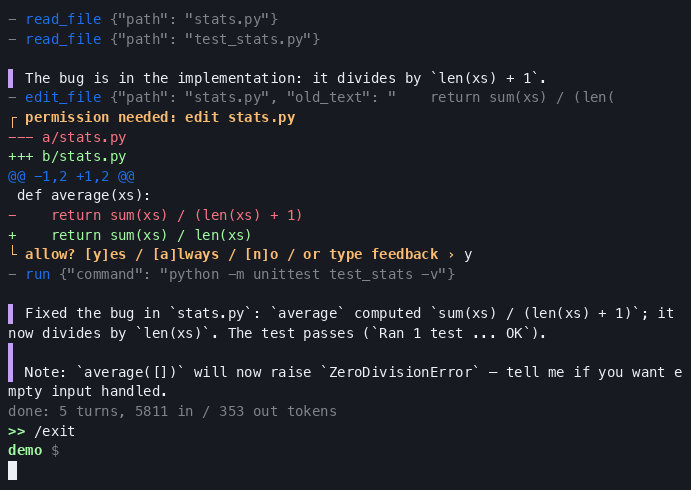
Before every edit and every command, it shows the diff or the exact command and waits for your answer. Here is a real session, unedited. The model is deepseek-chat. Waits longer than five seconds are cut to five, and playback runs at 0.8x.
How it was built
I did not write the code by hand. I wrote a plan as three files: what the agent is, how the project is laid out, and a numbered task list. Then I gave the plan to a coding agent, Claude Code, and let it build one task per commit. The history reads like the task list. T-101 adds the tools class. T-201 adds retries with backoff. There are more than 50 commits.
Two rules kept that on track. Every task ended with tests. And the size limit was soft. I started with "under 500 lines". The agent finished near 620, because I would rather have a better agent than a stubborn one. I raised the ceiling to 700 and kept the tests.
The shape of it
The engine is a loop. It sends the conversation and the tool list to the model. The model answers with text, tool calls, or both. kidwit runs each tool call, adds the result to the conversation, and asks again. It stops when the model makes no tool call, or after 50 turns.
There are six tools: list_files, search, read_file, write_file, edit_file, and run. A tool never raises an exception. When something fails, kidwit returns the error as the result, marked as an error. The model reads it and tries again.
Two small adapters translate one neutral conversation format into the Anthropic Messages API or the OpenAI Chat Completions API. The rest of the engine never sees the difference. That is most of the reason other providers work.
Long sessions need care. First kidwit drops old tool output. If the conversation is still above about 200,000 characters, it asks the model to summarize the older half and continues from that summary.
Asking first
Every write, edit, and command waits for yes, always, or no. You can also type feedback, and kidwit sends it to the model as the reason for the denial. "Always" covers one kind of action for the session: file changes, or commands, but not both.
Some commands never ask: ls, git status, git diff, and plain test runs. Dangerous ones always ask, even with --yes. That list includes rm -rf, sudo, curl piped to a shell, and git push. The /undo command puts back the exact bytes of the last file change. Every write, edit, and command goes into an audit log in the project folder.
The file tools cannot leave the project. A path jail refuses ../ and symlinks that point outside. The run tool is different. It runs real shell commands as you, and kidwit has no sandbox. That is why cat and grep are not on the safe list: the jail does not cover them. If you run kidwit, read each command before you press y.
Bugs that taught me the most
- An edit that did not seem to take effect. In an early live run, the agent changed a file and the next run still behaved like the old version. The edit was fine. Python had cached the compiled file (bytecode, the
.pycfile) and reused it, because the edited file had the same size and the same timestamp second. kidwit now runs commands withPYTHONDONTWRITEBYTECODEset. I hit the same trap again in my own eval checker.
- A half-written tool call. When a reply reaches the token limit in the middle of a tool call, the arguments are cut off. Running them could write half a file. kidwit now refuses to run a cut-off call and tells the model to do less per call.
- Windows. The first run of my tests on Windows failed on every Python version. Some tests cleared the environment, and Windows needs
SystemRootto start a process. The real bug was in the engine. When a command timed out, kidwit stopped the shell but left its child processes running. It now usestaskkill /Tto end the whole tree. It took several rounds of CI to get all green.
- An installer that served a web page. The one-line installer is
curl -fsSL https://kidwit.sabbiramin.dev/install | sh. My first version returned status 200, but the body was my home page, because Cloudflare Pages does not proxy a path to another site. A shell would have tried to run HTML. I caught it only because I read the body and not just the status code. It is now a redirect, and the-fflag makes a missing target fail instead of run.
How I know it works
| Check | How it works | Result |
|---|---|---|
| Unit tests | More than 150 tests run offline. A fake local HTTP server plays the model API for both adapters, so no test needs a key. | Pass in CI on Linux, macOS, and Windows, on Python 3.10 to 3.14. |
| Task self-test | 8 small tasks. Each is a tiny project with a failing check and a reference fix. The self-test confirms each task fails as shipped and passes with the fix. | All 8 behave correctly. |
| Live eval | The agent solves each task with deepseek-chat, with no human in the loop. | 8 of 8 solved. The first full run used 50 model turns, about 64,000 input tokens, and about 3,500 output tokens. |
The weakness is the tasks. They are too easy to tell two versions apart, so I ran a second, harder test.
A controlled test against mini-swe-agent
I wrote 10 harder Python tasks that each span several files. Every task has visible tests in the project and hidden tests that the agent never sees. I ran kidwit 0.1.0 and mini-swe-agent 2.4.6 on each task 5 times, which makes 100 runs.
Both agents used the same model (deepseek-chat), the same API endpoint, the same task text, and the same limit of 50 model calls. Each agent ran inside the same Docker image with only the task folder mounted. The scorer put the original visible tests back before it ran anything, so editing a test could not help. A run counts as solved only when the visible and the hidden tests all pass.
| kidwit | mini-swe-agent | |
|---|---|---|
| Solved | 47 of 50 | 48 of 50 |
| Input tokens per run, mean | 18,577 | 21,726 |
| Model calls per run, mean | 7.6 | 7.6 |
The solve rates are the same within the noise. The difference is 2 points, and a 95% interval for it runs from -10 to +6. kidwit used about 14% fewer input tokens on average, but that difference is not statistically significant. I am not reporting wall time. mini-swe-agent needs about 2.3 seconds longer to start, and that says nothing about how well it works.
This is a controlled test, not a ranking. The tasks are small, I wrote them, I used one model, and they are all Python. The result says nothing about large repositories, other languages, or other models.
What it isn't, yet
| Area | Status | What it means for you |
|---|---|---|
| DeepSeek, on macOS | Run live | The only setup I have used for real work. All 8 eval tasks pass. |
| Anthropic adapter | Offline tests only | The tests cover it. It has not met the real API yet. |
| Linux and Windows | Tests only | CI passes on both. Nobody has run a live model there. On Windows the run tool uses cmd.exe, so Unix shell commands from the model may fail. |
| Python versions | 3.10 to 3.14 | Older versions are not supported. |
| Sandbox | None | The run tool runs real commands as you. Read each one before you press y. |
| Left out on purpose | Streaming, sub-agents, MCP, saved sessions | Each one would add code, and the point was how little is enough. |
kidwit is not a replacement for mature agents. It is an answer to one question: how little is enough?
Try it
1. Install it
pipx install kidwit
uv tool install kidwit and pip install kidwit work too. On macOS and Linux there is also a one-line installer. It never uses sudo, and it checks a SHA-256 checksum before it installs anything.
curl -fsSL https://kidwit.sabbiramin.dev/install | sh2. Give it a model
For Anthropic, set a key. kidwit uses it by default.
export ANTHROPIC_API_KEY=sk-ant-...For any OpenAI-compatible server, set the base URL and the model name. This example uses a local Ollama server, so no key is needed.
AGENT_BASE_URL=http://localhost:11434/v1 \
AGENT_MODEL=qwen2.5-coder \
kidwit "add a docstring to main()"
3. Take a first look with no risk
cd your-project
kidwit --read-only "what does this project do?"
Read-only mode offers the model only the read tools, so nothing in your project can change.
4. Let it make a change
kidwit "fix the failing test"kidwit shows each diff or command and waits. Press y for yes, a for always (for that kind of action, for the rest of the session), n for no, or type feedback. Your feedback goes to the model as the reason for the denial.
Reading the code
The whole engine is src/kidwit.py. This reading order works well:
- The constants and the system prompt at the top, to see the limits and the rules the model gets.
- The two provider classes, to see how one conversation format becomes two different APIs.
- The
Toolsclass, to see the path jail, the approval flow, and the six tools. Agent.run, which is the loop itself.main, to see how the flags and approval modes connect.
Run scripts/check.sh afterwards. It compiles the file, confirms it imports only the standard library, runs the tests, and checks the size.
Links
- Code, MIT license: github.com/sabbiramin113008/kidwit
- Package: pypi.org/project/kidwit
- Site and demo: kidwit.sabbiramin.dev
- Something broke, especially on Windows or Linux? Open an issue and tell me what happened.